Xia Su Presents CapNav at CVPR
Congratulations to Xia Su and co-authors on "CapNav: Benchmarking Vision Language Models on Capability-conditioned Indoor Navigation," published in the CVPR 2026 main track!
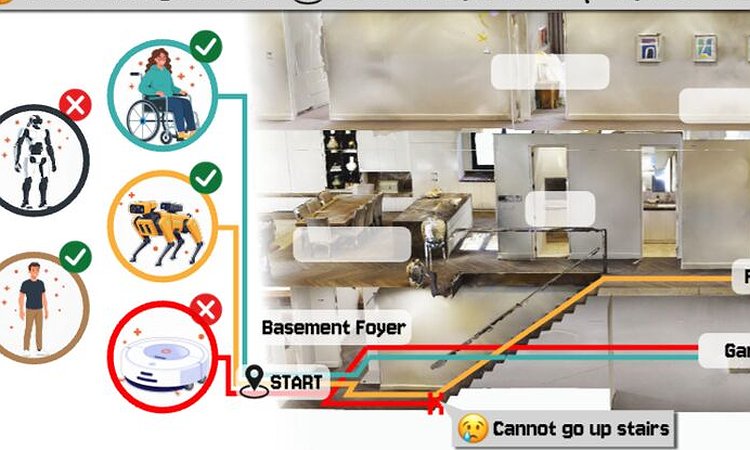
A route that works for one person can be impossible for another. CapNav asks whether today's vision language models (VLMs) can plan indoor routes that respect an agent's physical capabilities. The benchmark covers 45 real-world indoor scenes and 2,365 navigation tasks across five embodiments: a person walking, a wheelchair user, a humanoid robot, a quadruped robot, and a sweeping robot. Evaluating 13 state-of-the-art VLMs, the team found that performance drops sharply as mobility constraints tighten, and that geometry-sensitive constraints, such as narrow passages, defeat every model tested.
CapNav was led by Xia Su with Ruiqi Chen, Benlin Liu, Jingwei Ma, and Zonglin Di, advised by Jon Froehlich and Ranjay Krishna. The code is on GitHub.